Data Scientist · Medline Industries

Rajeshwar Rathi

Data Scientist · ML & Data Engineering

Data scientist with 5+ years building machine learning systems, retrieval and data pipelines in Python.

About

I build machine learning systems and the data infrastructure that keeps them fed.

I graduated from the College of Engineering, Pune in 2020 with a B.Tech in Computer Science. An internship at Veritas shaped what I wanted to work on — an impact-analysis engine that mapped the dependencies between microservices and scored what would break if any one of them went down.

I spent the five years after graduating at Bitwise, working across several clients. The first couple of years were data engineering — pipelines, warehouses and the unglamorous plumbing that makes analytics trustworthy — and the last of them were spent as a machine learning engineer for a payment technology client, taking models from notebook to production. Along the way I finished a PG Diploma in Data Science at IIIT Bangalore, which is where a long-standing interest in deep learning turned into something I could actually ship.

I am now a data scientist at Medline India, building product intelligence and search over the product catalogue with GraphRAG — pairing a knowledge graph of how products relate to each other with LLM-based retrieval, so that a search can follow those relationships rather than just match text.

Day to day that means Python and GraphRAG; Azure CosmosDB, ML Studio and Microsoft Fabric; PyTorch and TensorFlow when there is a model to train, and a good deal of time on knowledge graphs and retrieval quality. I care about systems that are boring to operate and easy to reason about six months later.

This site is also where I write. Expect posts on applied AI, data science and cloud engineering — the things I had to figure out the hard way, written down so the next person does not have to.
Toolkit

Languages
  • Python
  • C++
  • C
  • SQL
  • JavaScript
  • LaTeX
Machine Learning
  • PyTorch
  • TensorFlow
  • Keras
  • scikit-learn
  • Regression & classification
  • Ensembles (Random Forest, XGBoost)
  • Clustering (k-NN, k-Means)
  • Regularisation & cross-validation
  • Hyperparameter tuning
Deep Learning
  • CNNs
  • GANs
  • VAEs
  • Vision Transformers
  • RNN / LSTM / GRU
  • Optimizers
LLMs & Retrieval
  • GraphRAG
  • Retrieval-augmented generation
  • Knowledge graphs
  • Embeddings & vector search
  • Semantic search
Data & ETL
  • PySpark
  • Apache Airflow
  • Azure Data Factory
  • Snowflake
  • Redshift
  • S3
  • Pandas
  • NumPy
Cloud
  • Azure (Batch, Functions, Data Factory, Key Vault, Blob Storage)
  • AWS (SageMaker, EC2, S3, Redshift, IAM, MWAA)
Tooling
  • Git
  • Docker
  • Jenkins
  • Azure DevOps
  • JIRA
  • Agile / Scrum
  • Postman
Visualisation
  • Matplotlib
  • Seaborn
  • Plotly
  • NetworkX
  • GraphViz

Experience

  1. to · Pune, India

    Data Scientist at Medline Industries

    Building a Product Intelligence API over the product catalogue with GraphRAG and LLMs.

    • Co-developing a Product Intelligence API using GraphRAG (Graph Retrieval-Augmented Generation) and LLMs to automate product discovery and power intelligent recommendations for the business unit.
    • Leveraged knowledge graphs and community-detection algorithms to drive next-generation AI recommendations in Product Intelligence.
    • Designing and implementing a scalable graph database in Azure CosmosDB to model complex product relationships and hierarchies.
    • Managing the end-to-end ML lifecycle (MLOps) with Azure ML Studio and Azure DevOps, streamlining model training and deployment.
    • Leveraging Microsoft Fabric for unified data integration and analytics.
    • Python
    • GraphRAG
    • LLMs
    • Azure CosmosDB
    • Azure ML Studio
    • Microsoft Fabric
  2. to · Pune, India

    Python Developer (PySpark, Big Data) at Bitwise Inc.

    Migrated Informatica ETL workflows to PySpark and modernised on-premise pipelines onto Azure.

    • Migrated and optimised complex Informatica workflows into PySpark ETL pipelines and modular Python APIs, handling Delta tables and XML files.
    • Deployed solutions on Microsoft Fabric, achieving a 20% performance improvement in data processing.
    • Modernised on-premise Python scripts by migrating them to Azure Cloud, integrating Snowflake, MSSQL and AWS S3, which reduced costs by 60%.
    • Built secure ETL pipelines for PII data handling from Sybase/MSSQL to Snowflake, cutting processing time by 40%.
    • Developed a zero-downtime Azure Function App for automated ServiceNow ticket creation on ADF pipeline failures, improving incident response.
    • Python
    • PySpark
    • Delta Lake
    • Azure
    • Microsoft Fabric
    • Snowflake
  3. to · Pune, India

    Machine Learning Engineer at Bitwise Inc.

    Built an ML pipeline to identify repeat callers, cutting customer-support costs by up to $1M.

    • Developed an end-to-end ML pipeline in Python and AWS SageMaker to identify repeat callers, enabling cost-effective customer engagement and reducing costs by up to $1 million.
    • Ran hypothesis testing, visualisation, data imputation, balancing and cross-validation, reaching 82% prediction accuracy.
    • Optimised data processing with SQL views in Snowflake and PySpark on AWS EMR, resulting in 4x faster analysis.
    • Python
    • AWS SageMaker
    • PySpark
    • AWS EMR
    • Snowflake
  4. to · Pune, India

    Data Engineer at Bitwise Inc.

    Airflow-based ETL pipelines feeding AWS Redshift, and Informatica-to-ADF migrations.

    • Streamlined Airflow-based ETL pipelines on EC2 for automated data extraction from S3 to AWS Redshift, enabling business-metric evaluation.
    • Standardised 30+ Informatica workflows to Azure Data Factory, integrating Oracle and Synapse data sources to reduce latency.
    • Python
    • Airflow
    • AWS Redshift
    • Azure Data Factory
    • EC2
  5. to · Pune, India

    SDE Intern at Veritas LLC

    Built an impact-analysis engine that mapped dependencies between microservices.

    • Parsed service configuration and log files to generate a dependency graph of a microservice architecture using NetworkX and GraphViz.
    • Derived an impact score for each service — how much of the system degrades if it goes down — weighted by service centrality and bug severity.
    • Wired the tool into CI so the graph regenerated on every build instead of being redrawn by hand.
    • Python
    • NetworkX
    • GraphViz
    • Plotly
    • Jenkins

Projects

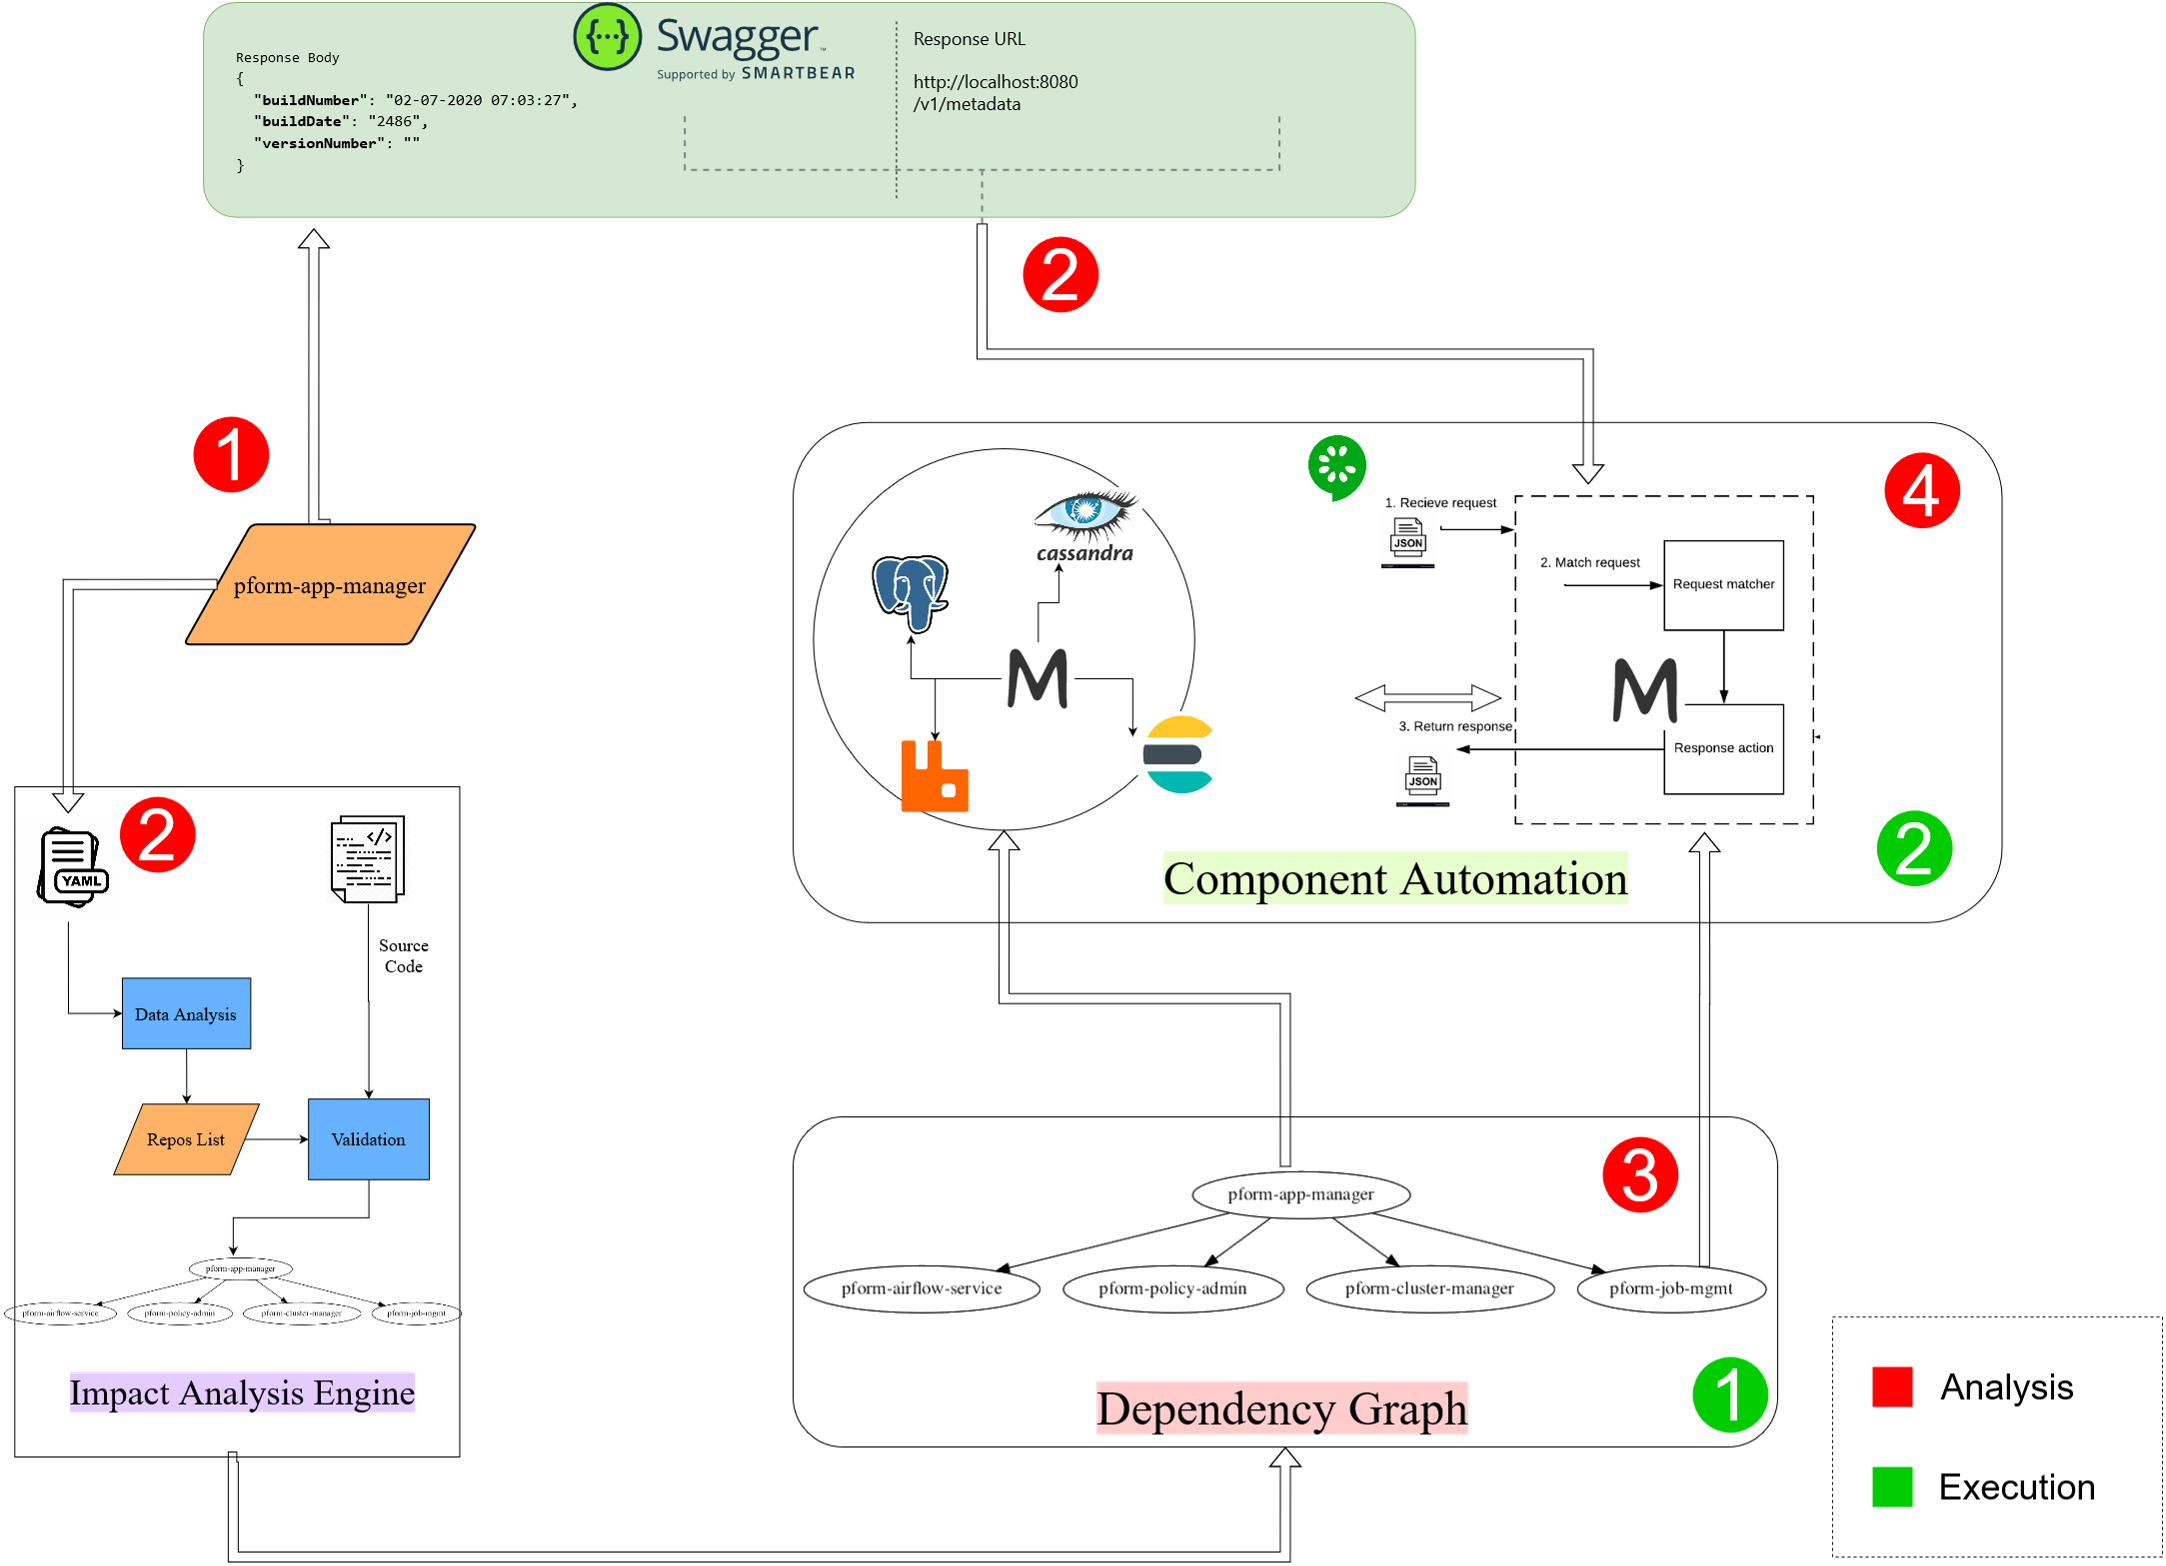
  • Directed dependency graph of microservices

    Impact Analysis Engine for Microservices

    2020

    A utility that reads service config and log files and builds a live dependency graph of a microservice architecture. Each service gets an impact score — how much of the system degrades if it goes down — weighted by its position in the graph and the severity of open bugs against it. Cut the latency of component-automation decisions considerably.

    • Python
    • NetworkX
    • GraphViz
    • Plotly
    • Pandas
    • Jenkins
    • CI/CD
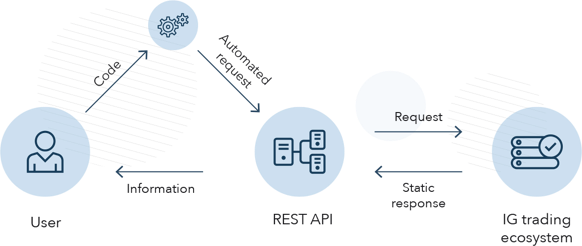
  • Trading platform order book screen

    Mock Trading System

    2019

    A team-built stock trading platform. I owned exchange connectivity — the REST layer that moved orders and fills between the front end and the matching engine.

    • Python
    • Flask
    • C++
    • SQLite
    • REST
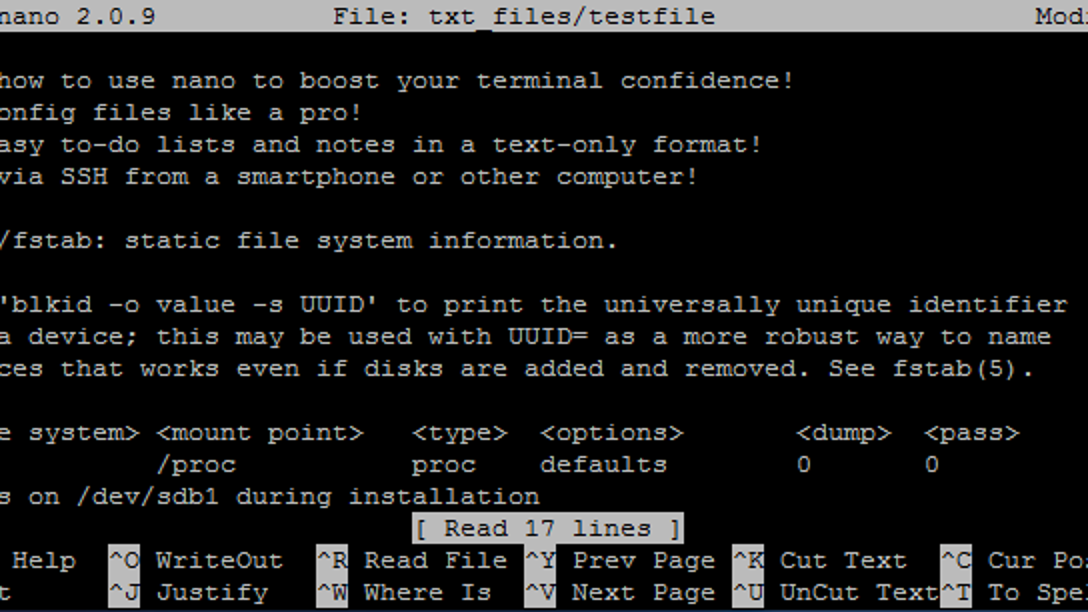
  • Terminal text editor showing a file open

    Terminal Text Editor

    2018

    A modal text editor for the terminal written in C against ncurses, with find, search-and-replace, line operations and file I/O. The kind of project that teaches you what a buffer really is.

    • C
    • ncurses
    • regex

Latest writing

All posts

Contact

Let's build something.

I am always up for talking about applied ML, data platforms, or a good retro-computing rabbit hole. The fastest way to reach me is email.